01 / Speech synthesis
RESONANCE
A scratch-trained speech model you can listen to.
Six saved phrases · zero inference cost per visit
Speech desk / six saved generations
Give the voice a line.
Type a recorded line or choose one below. Hear its output from the trained model, generated locally and saved for this exhibit.
Select or type one of the six saved lines. Your text stays in this browser.
Loading the recorded phrase collection…
Generated from acoustic checkpoint step 17,500 and vocoder checkpoint step 20,000.
Reading the signal
Text
A character sequence enters the acoustic model. The six phrases here were generated from the saved checkpoint.
Sound
The model predicts 80-band mel features; a vocoder turns them into the waveform you hear.
Plot
The training figure tracks mel error over optimizer updates. Listening reveals timing and pronunciation details that one loss value cannot describe.
Training record
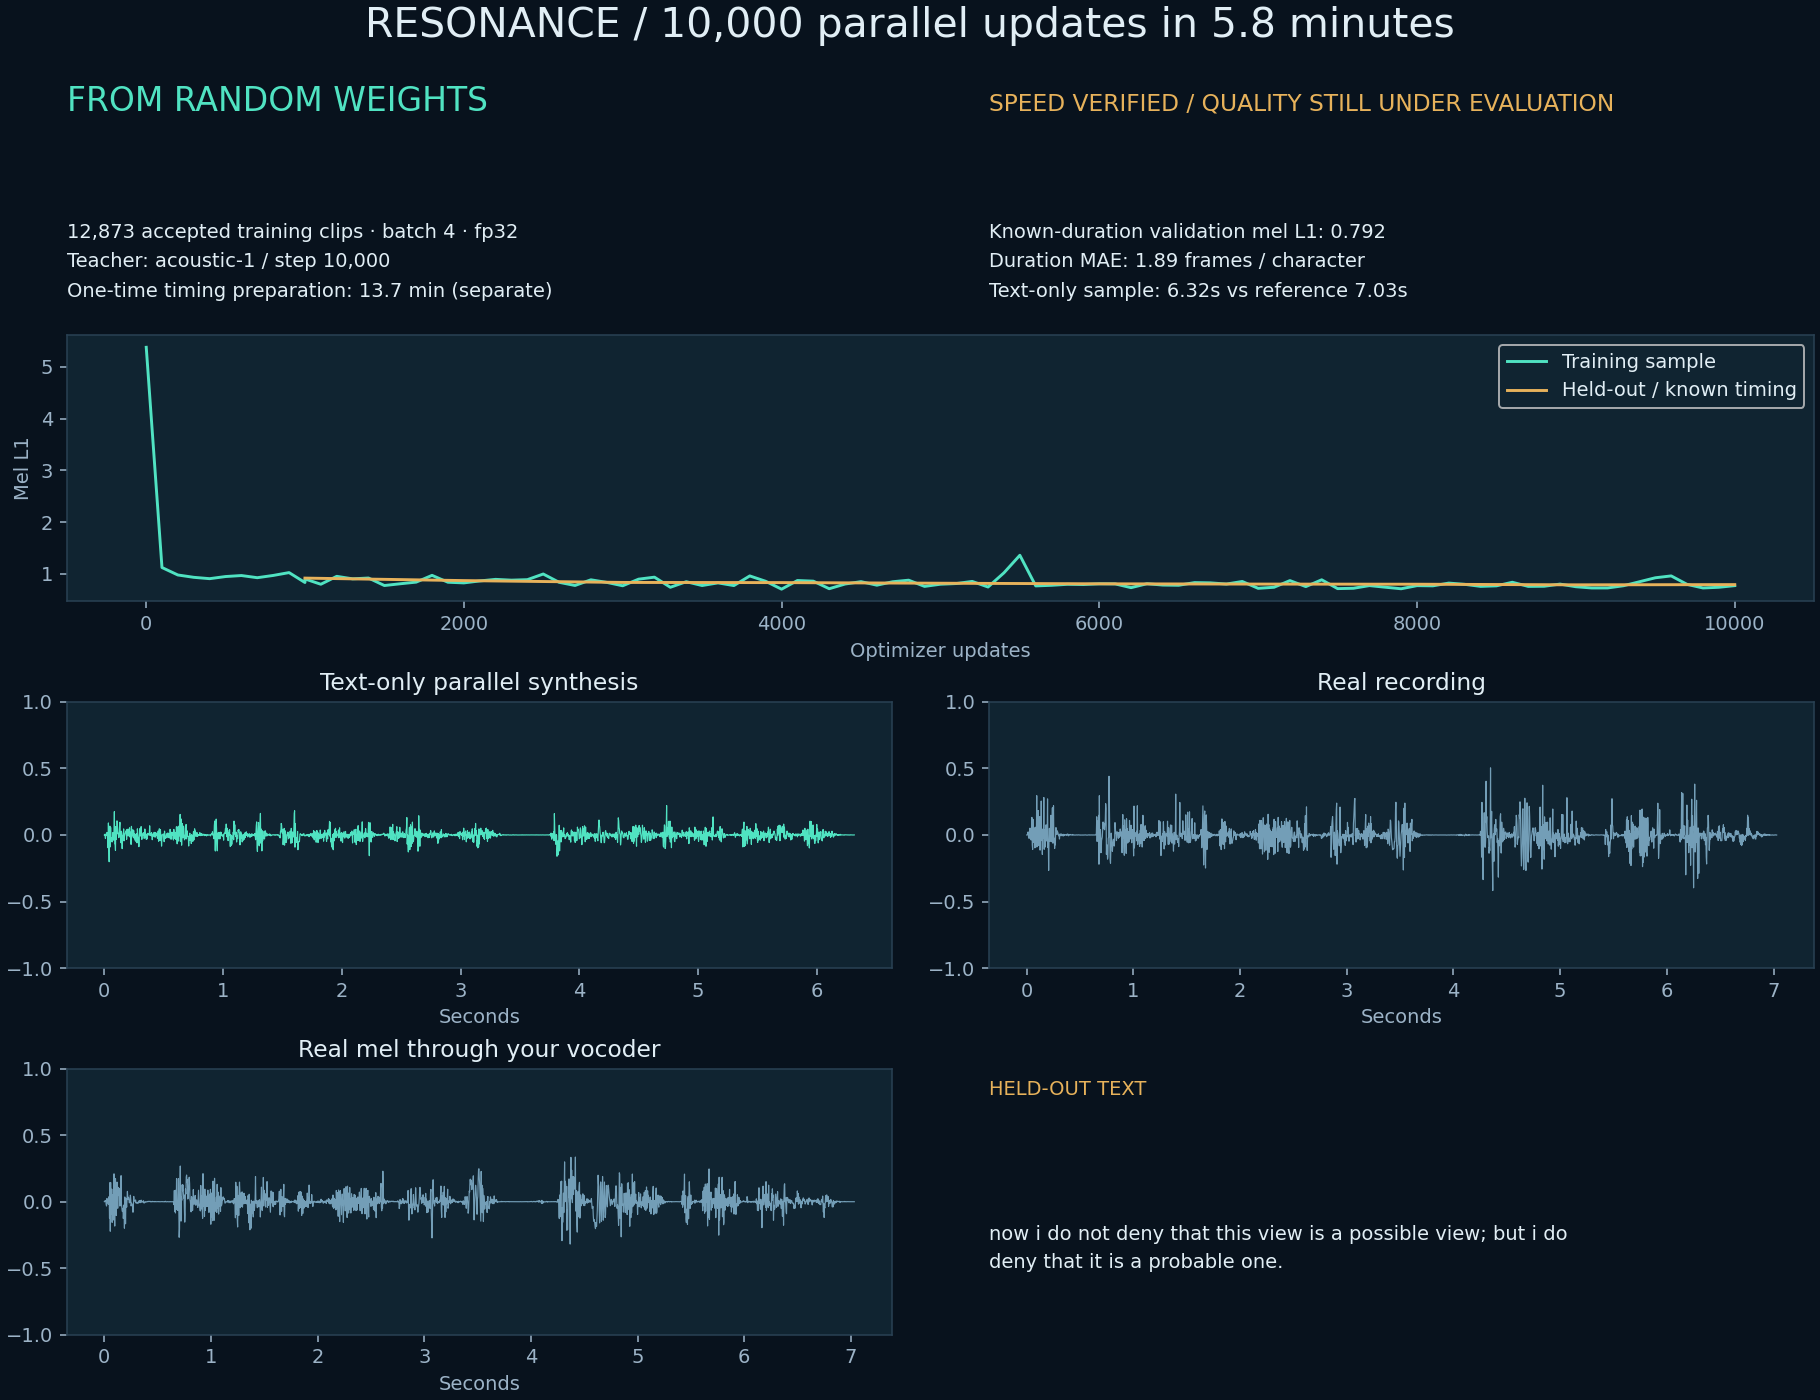
RESONANCE maps text to a mel spectrogram, then turns that spectrogram into audio. Its acoustic and waveform models were trained from random initialization on LJ Speech.
The listening desk contains six saved generations. The waveform shows each clip's amplitude over time; the training figure above shows the acoustic model's measured learning curve.
See the local observatory
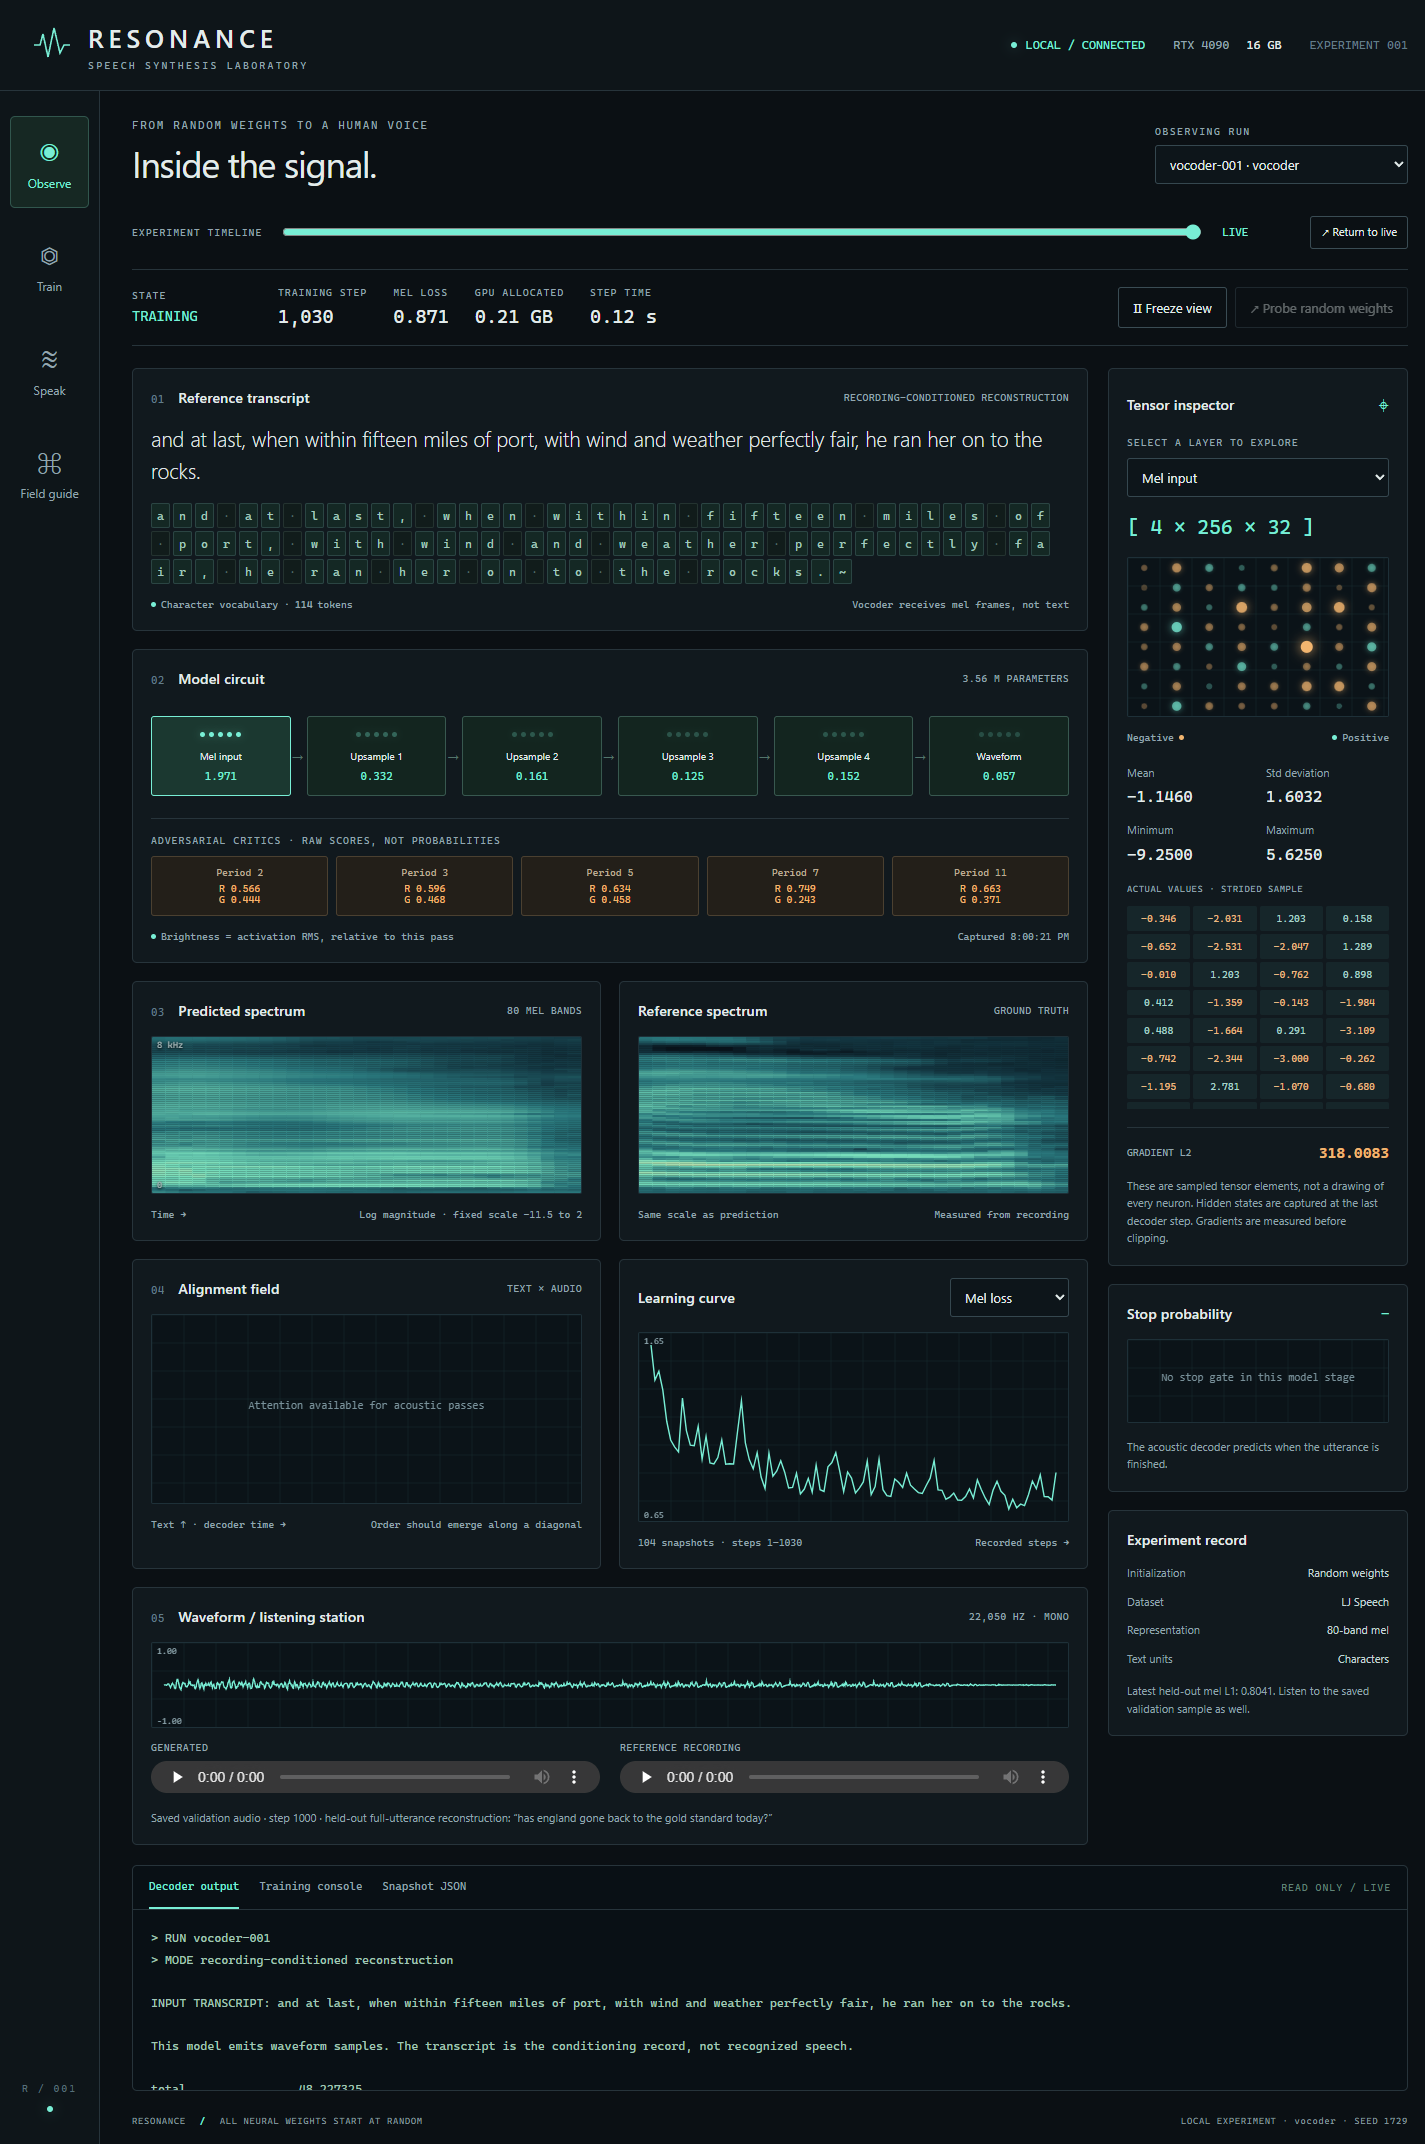
This screenshot is a recorded view of the research instrument.