05 / Continual learning
Plastic Signal Garden
Watch a recurrent agent and its fast weights as the beacon rule changes.
Saved checkpoint replay · arena and neural telemetry
05 / Checkpoint replay
Inside Signal Garden.
The white agent chooses actions as the rewarded beacon changes. The panels show recorded activity from the same model step.
Recurrent activity
24 sampled unitsFast weights
Memory slots
Loading saved episode…
Recorded from garden_200k_v2 / best checkpoint. Fixed seeds 118–120; 320 steps each. Colors indicate activity magnitude, not new connections.
Activity through the episode
The project
Three timescales of state
The agent has slow learned recurrent weights, fast Hebbian weights updated at each step, and twelve gated memory slots. A cue selects a rewarded beacon; the cue-to-beacon mapping changes once during each episode.
Observations & lessons
What the replay reveals
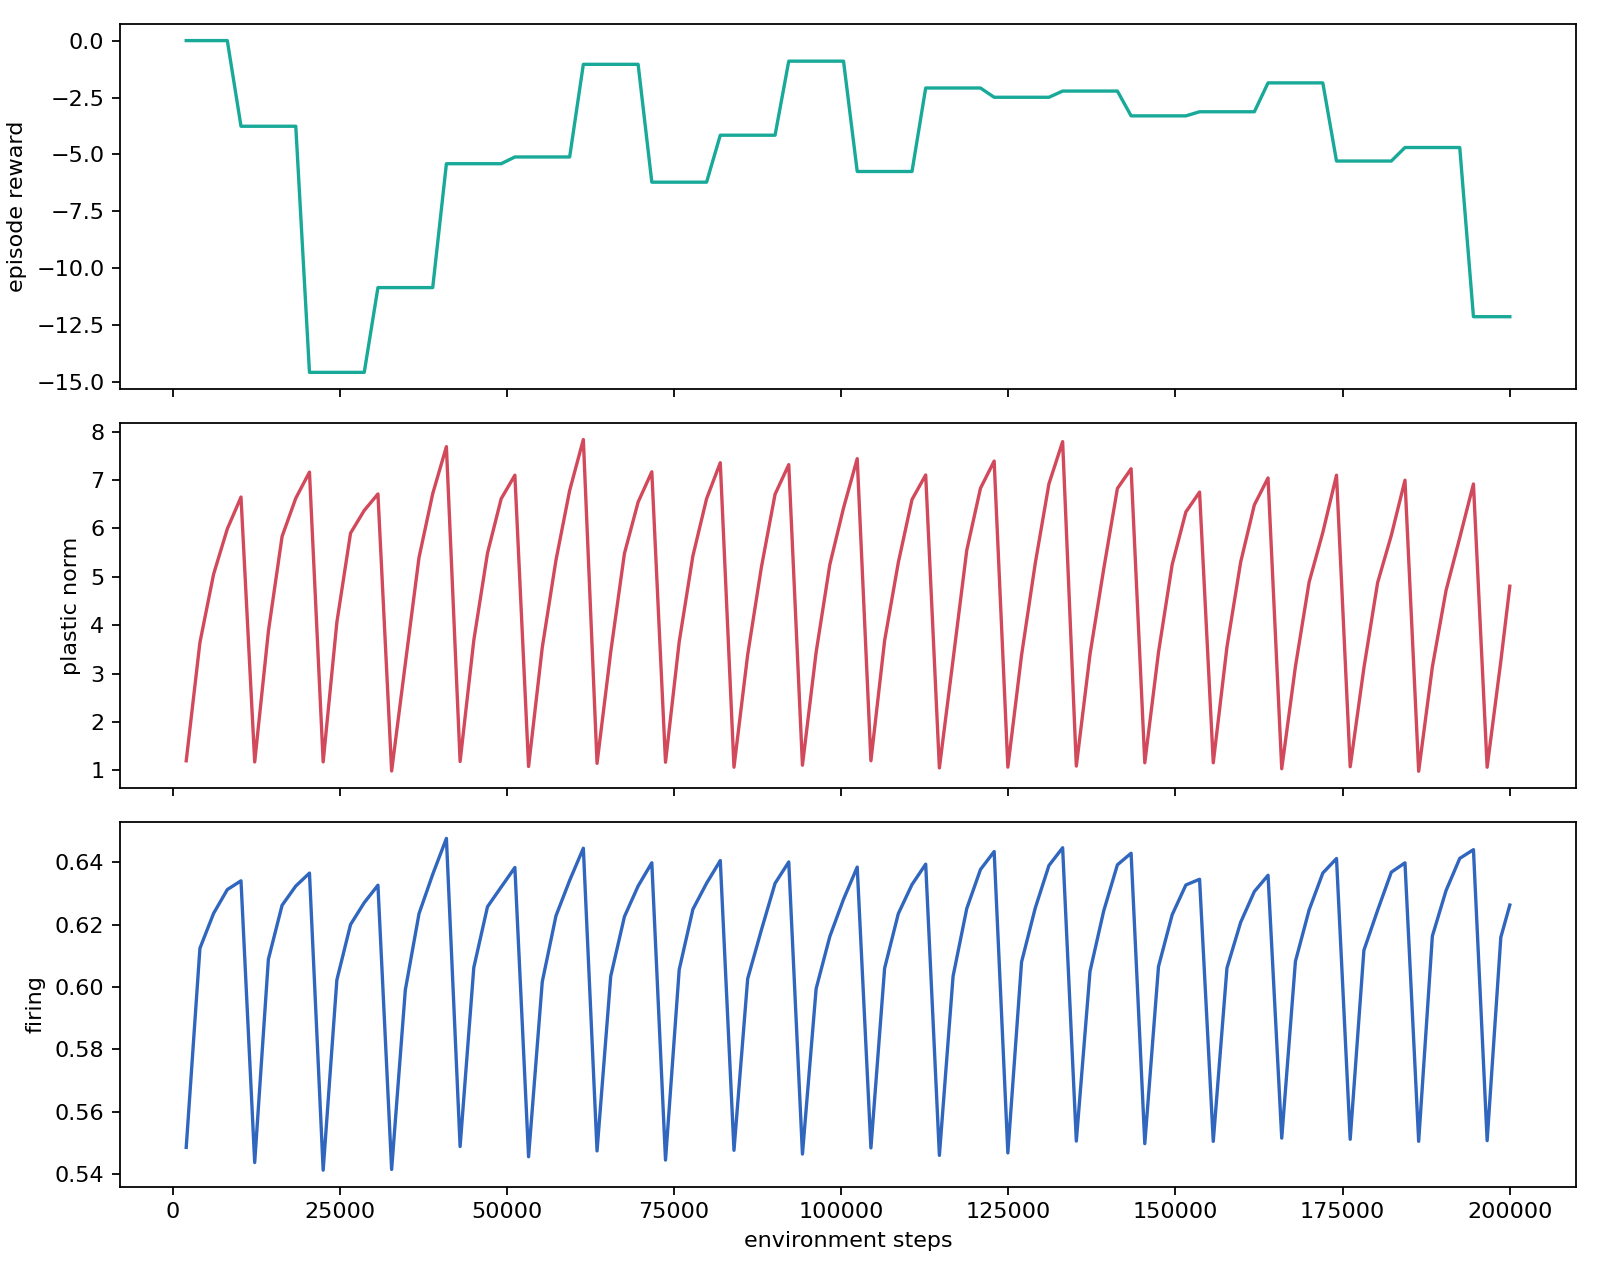
Neural activity and plastic weights remain active when the rule changes. In these three fixed replays, the selected checkpoint collects zero goals. The training run also finishes with negative episode reward. The next useful test is whether plasticity improves navigation over the same recurrent model with fast weights disabled.
Recorded training
The 200,000-step run.