03 / Action learning
ARCHON REFLEX
One action model tested in Doom and control tasks.
Five saved agent episodes · frozen evaluation
Saved policy episodes / fixed evaluation seeds
Watch the agent act.
Each recording follows the released REFLEX policy through one evaluation episode. Choose a task, play it, or move through the timeline. The reported figures summarize the wider evaluation set.
Currently viewing
Health gathering
The agent navigates from RGB frames, public health, and heading. Its goal is to collect health and survive a 60-second episode.
An explicitly trained scenario. Recording: first declared final seed.
Ready to play the saved health gathering episode.
Frozen experiment / fixed final contexts
What did replay preserve?
Choose a task to compare normalized immediate-reward gain after the adaptation sequence. The measurements are from the saved Cycle 3 research summary.
Replay retained more of Dock's measured gain.
Saved Cycle 3 outcomes in fixed final contexts.
Recorded plots
Two views of adaptation
Reading the agent
Input
Doom episodes use a learned RGB encoder plus public game state. The arm task uses engineered numeric observations.
Choice
A shared model scores the available actions. The recordings show the frozen released policy at fixed evaluation seeds.
Evidence
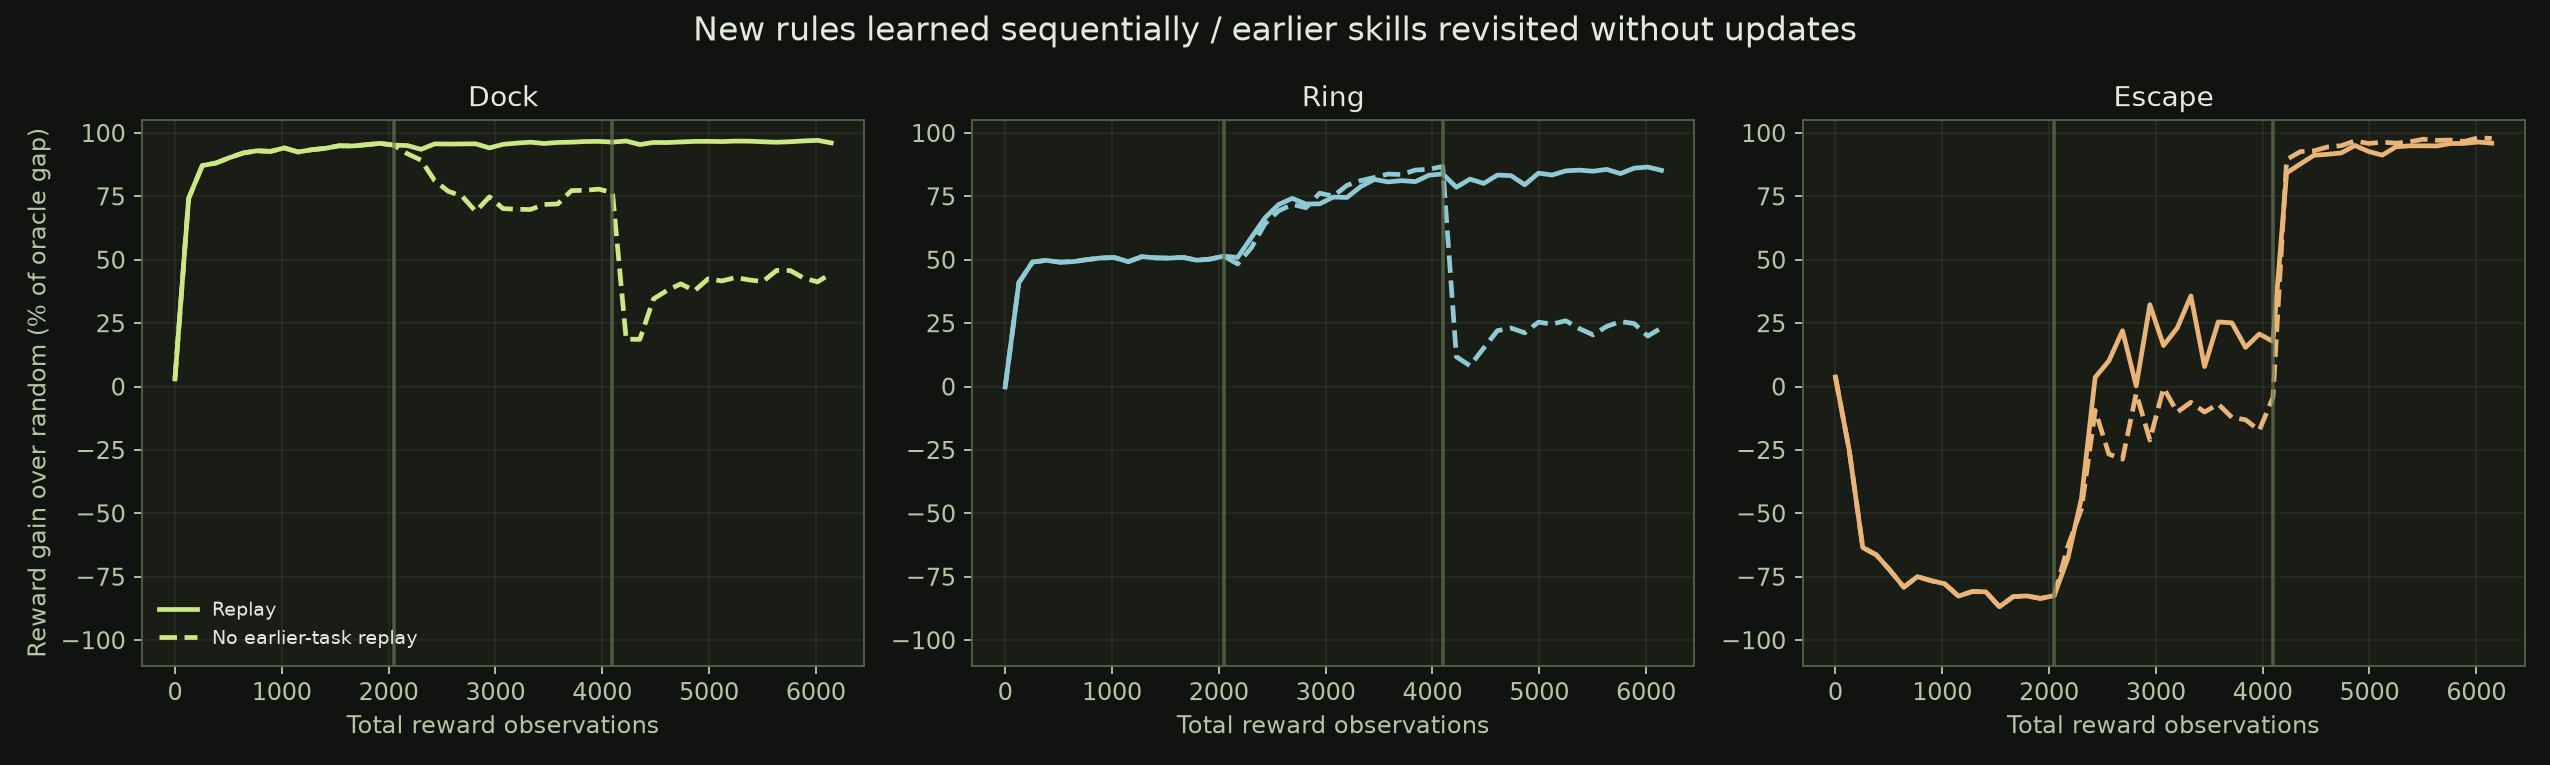
Each video is one episode. The adjacent figures summarize 50 matched Doom seeds or 512 control episodes; the plot follows sequential reward learning.
REFLEX uses a shared model to score available actions from an observation and a goal. The recordings show its released policy in four ViZDoom scenarios and a kinematic reaching task.
Across 50 matched Doom seeds, Arena rose from 3.30 to 8.36 mean kills, while Defend the Line fell from 14.84 to 12.92. The replay comparison above measures how earlier learned reward rules held up after later updates.